Lectures
Slides and the papers discussed in each class are listed below.
-
-
Lecture 1 Internet with Agents
tl;dr: Coding agent workloads, WebSocket-based communication, and Model Context Protocol (MCP).
Reading list
- TraceLab: Characterizing Coding Agent Workloads for LLM Serving
- Speeding up agentic workflows with WebSockets in the Responses API
- Model Context Protocol
-
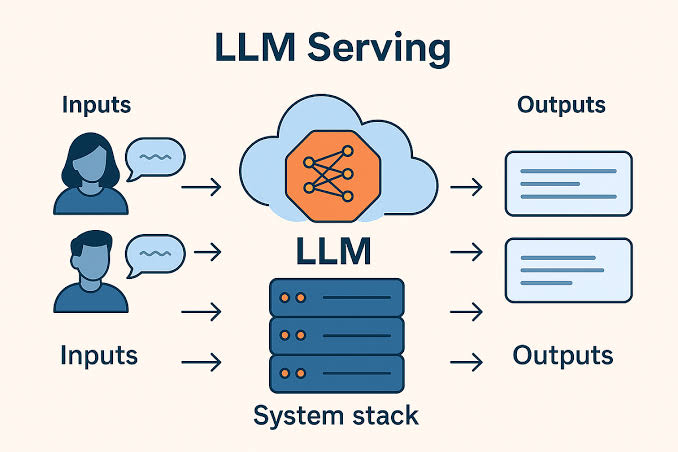
Lecture 2: LLM serving
tl;dr: KV cache memory management, inference scheduling, and disaggregated architectures for efficient LLM serving.
Reading list
- [SOSP'23] Efficient Memory Management for Large Language Model Serving with PagedAttention (slides)
- [OSDI'24] Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve (slides)
- [OSDI'24] DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving (slides)
- [FAST'25] Mooncake: Trading More Storage for Less Computation — A KVCache-centric Architecture for Serving LLM Chatbot (slides)
- [NSDI'26] Agentix: An Efficient Serving Engine for LLM Agents as General Programs (slides)
- [NSDI'26] JITServe: SLO-aware LLM Serving with Imprecise Request Information (slides)
- [NSDI'26] ServeGen: Workload Characterization and Generation of Large Language Model Serving in Production (slides)
-
Lecture 3: Networking for AI
tl;dr: In-network aggregation, collective communication algorithm synthesis, and performance simulation for distributed machine learning.
Reading list
- [NSDI'21] SwitchML: Scaling Distributed Machine Learning with In-Network Aggregation (slides)
- [NSDI'23] TACCL: Guiding Collective Algorithm Synthesis using Communication Sketches (slides)
- [NSDI'25] SimAI: Unifying Architecture Design and Performance Tuning for Large-Scale Large Language Model Training with Scalability and Precision